What Good Experimental Data Looks Like for R&D Machine Learning
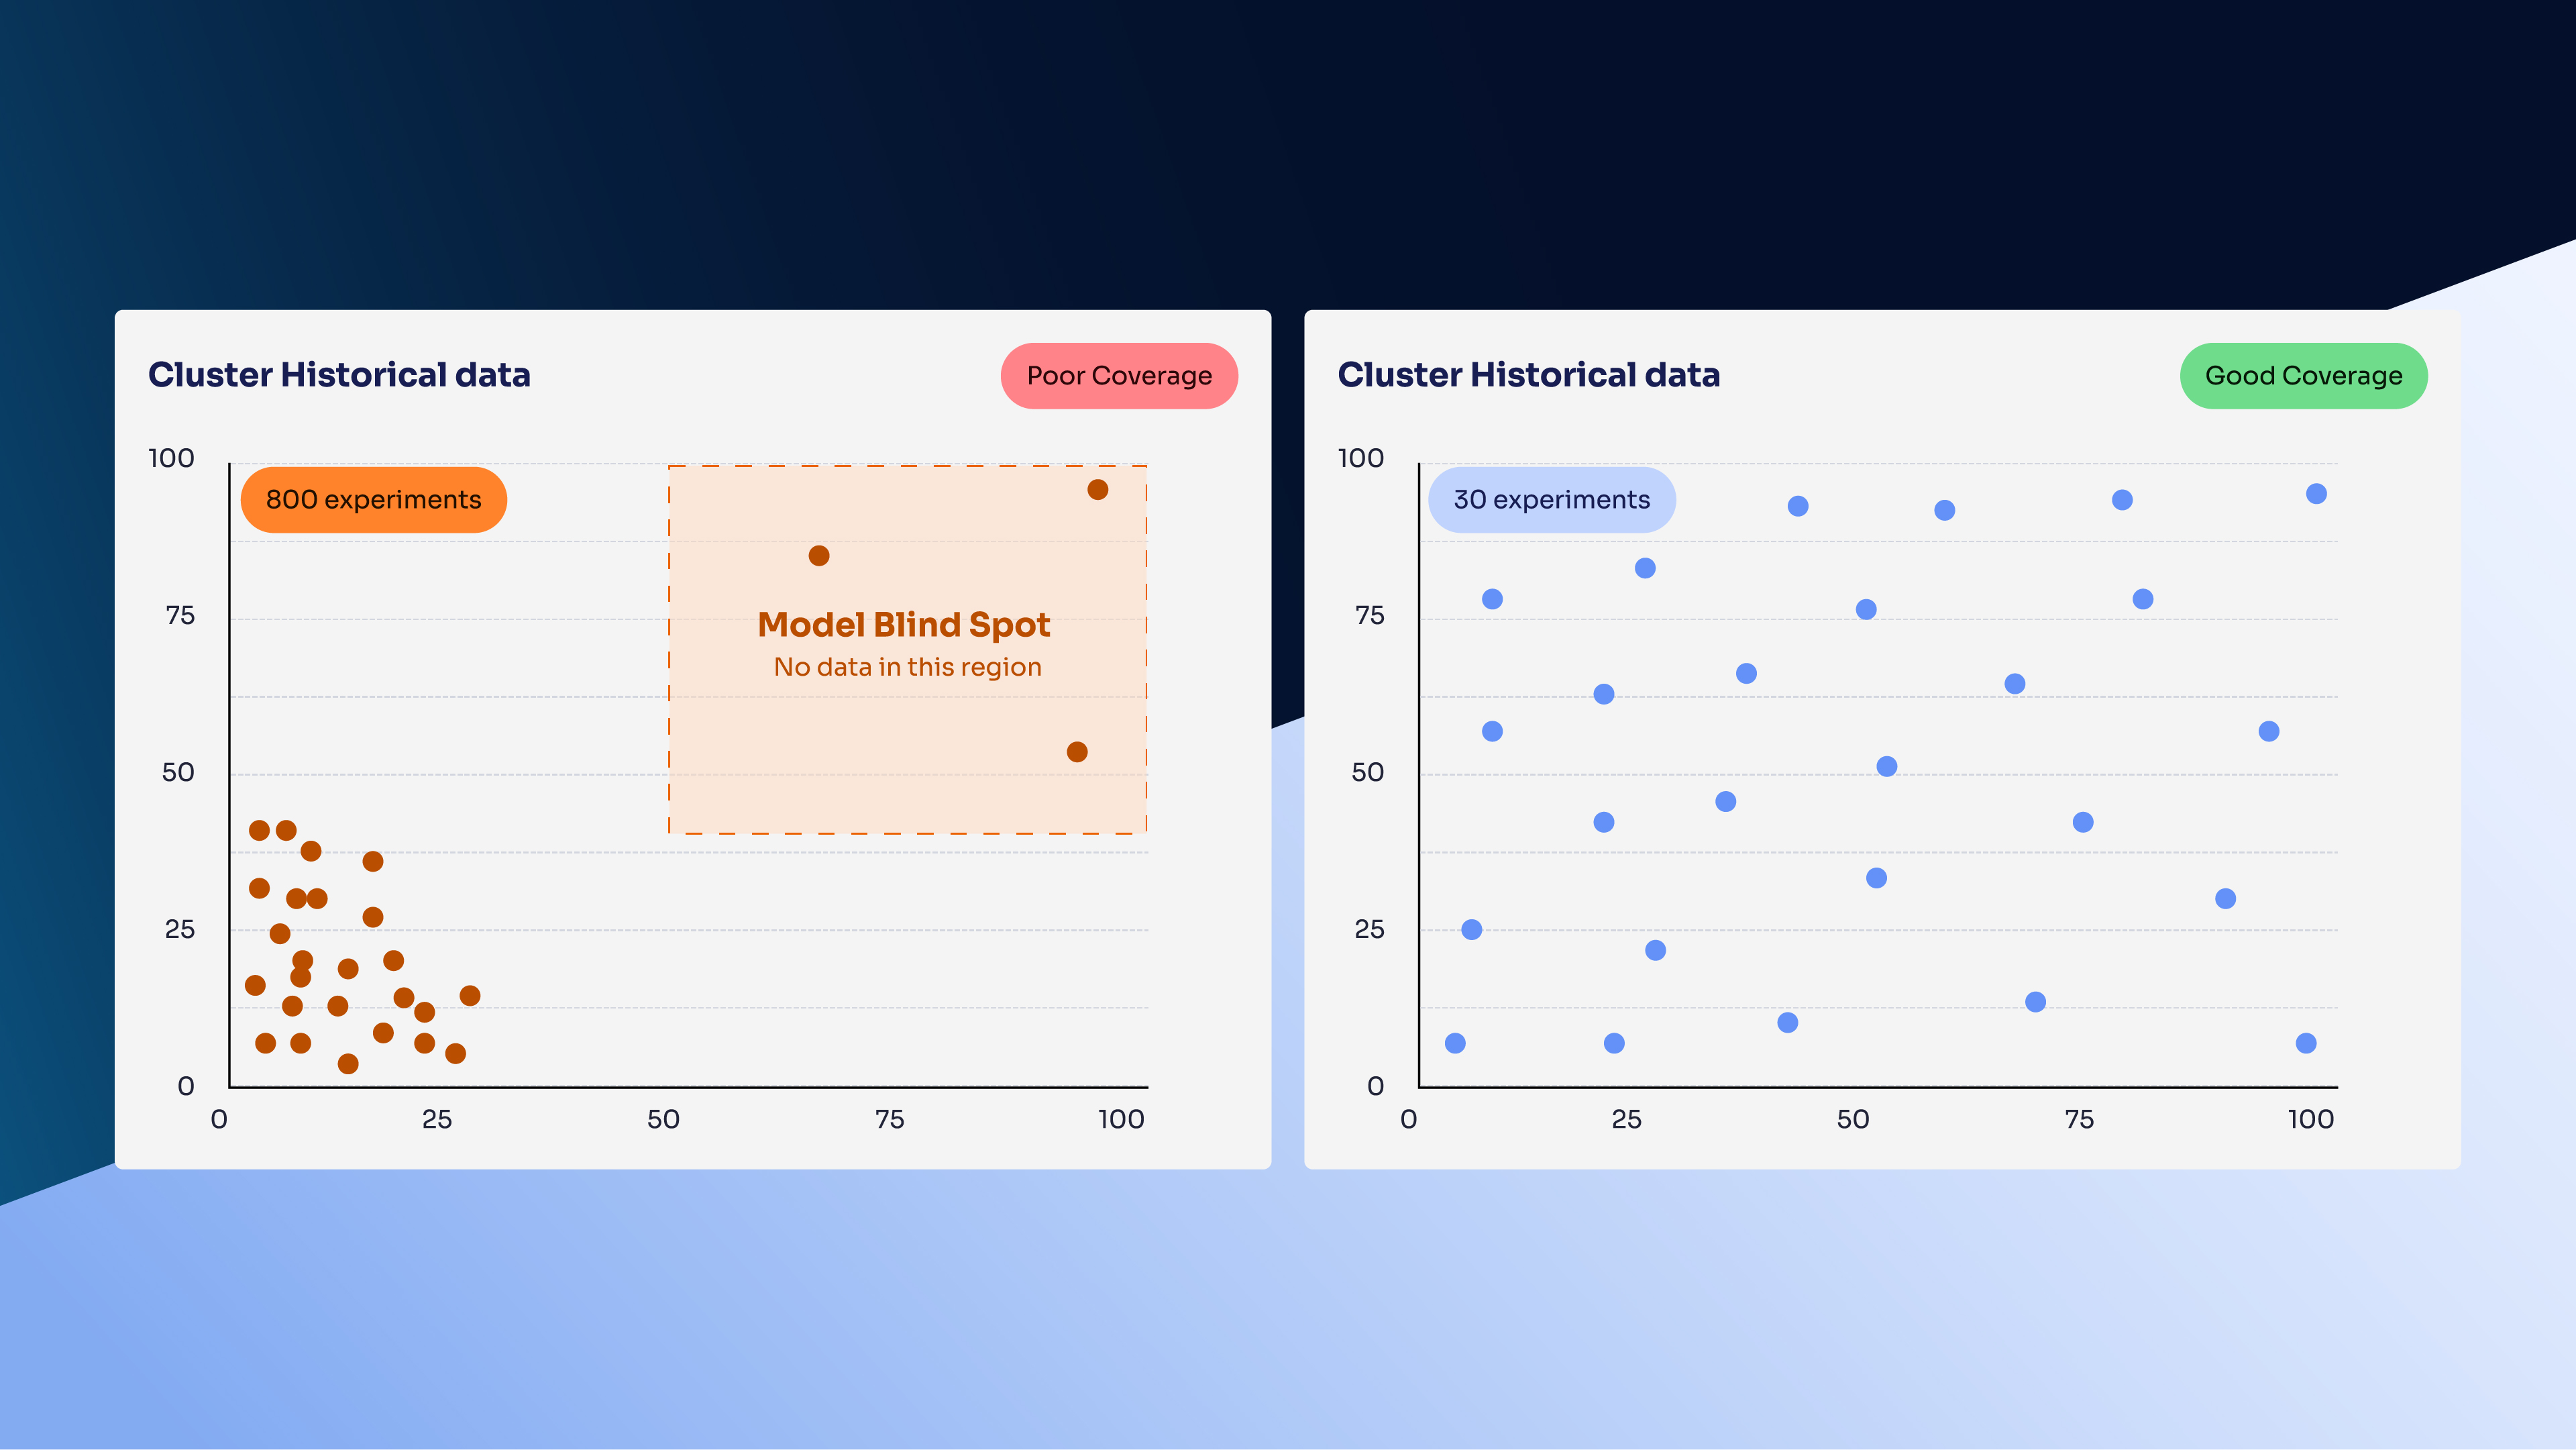
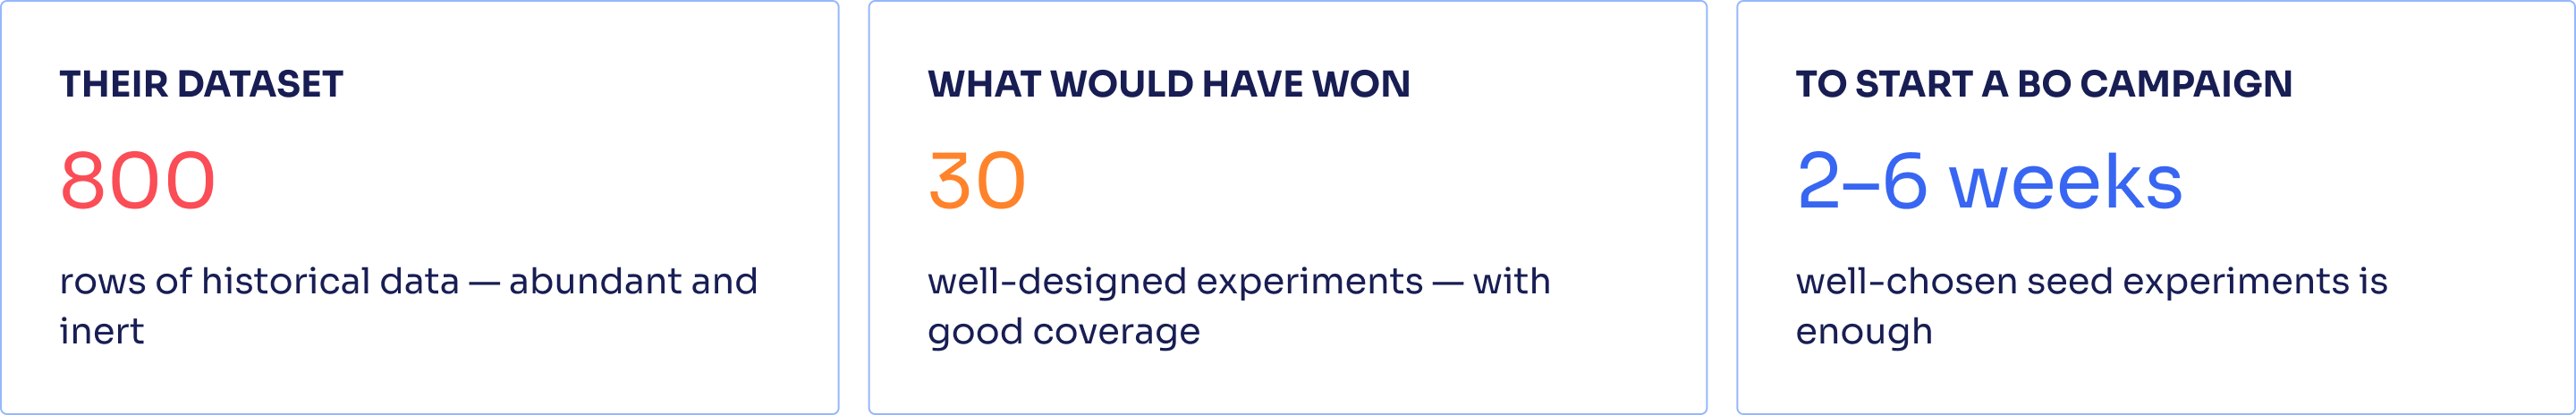
A pharma client handed us 800 historical reactions and asked for a model. The team had spent two years collecting the data. The model we built on it was useless — not because of sample size, but because of data quality.
Key Takeaways
- Data quality for R&D machine learning is defined by five characteristics: coverage, resolution, provenance, consistency, and structure. Row count is not on that list.
- A 30-point dataset that systematically explores the design space will outperform a 1,000-point dataset living in one corner of that space.
- The most common data quality failure in R&D ML is categorical-only parameterization — encoding chemicals as labels prevents a model from generalizing to anything new.
- For most BO campaigns, 5–15 well-chosen seed experiments is enough to start. 20–50 total experiments is usually enough to converge for moderate dimensionality (3–8 factors).
- Signal-to-noise is the single most under-discussed factor in R&D ML. Many model failures are assay failures, not algorithm failures.
- Sunk-cost bias keeps bad data alive in modeling pipelines for years. Starting over with 20–30 well-designed new experiments is often more productive than cleaning unsalvageable legacy data.
Why "More Data" Is the Wrong Frame for R&D Machine Learning
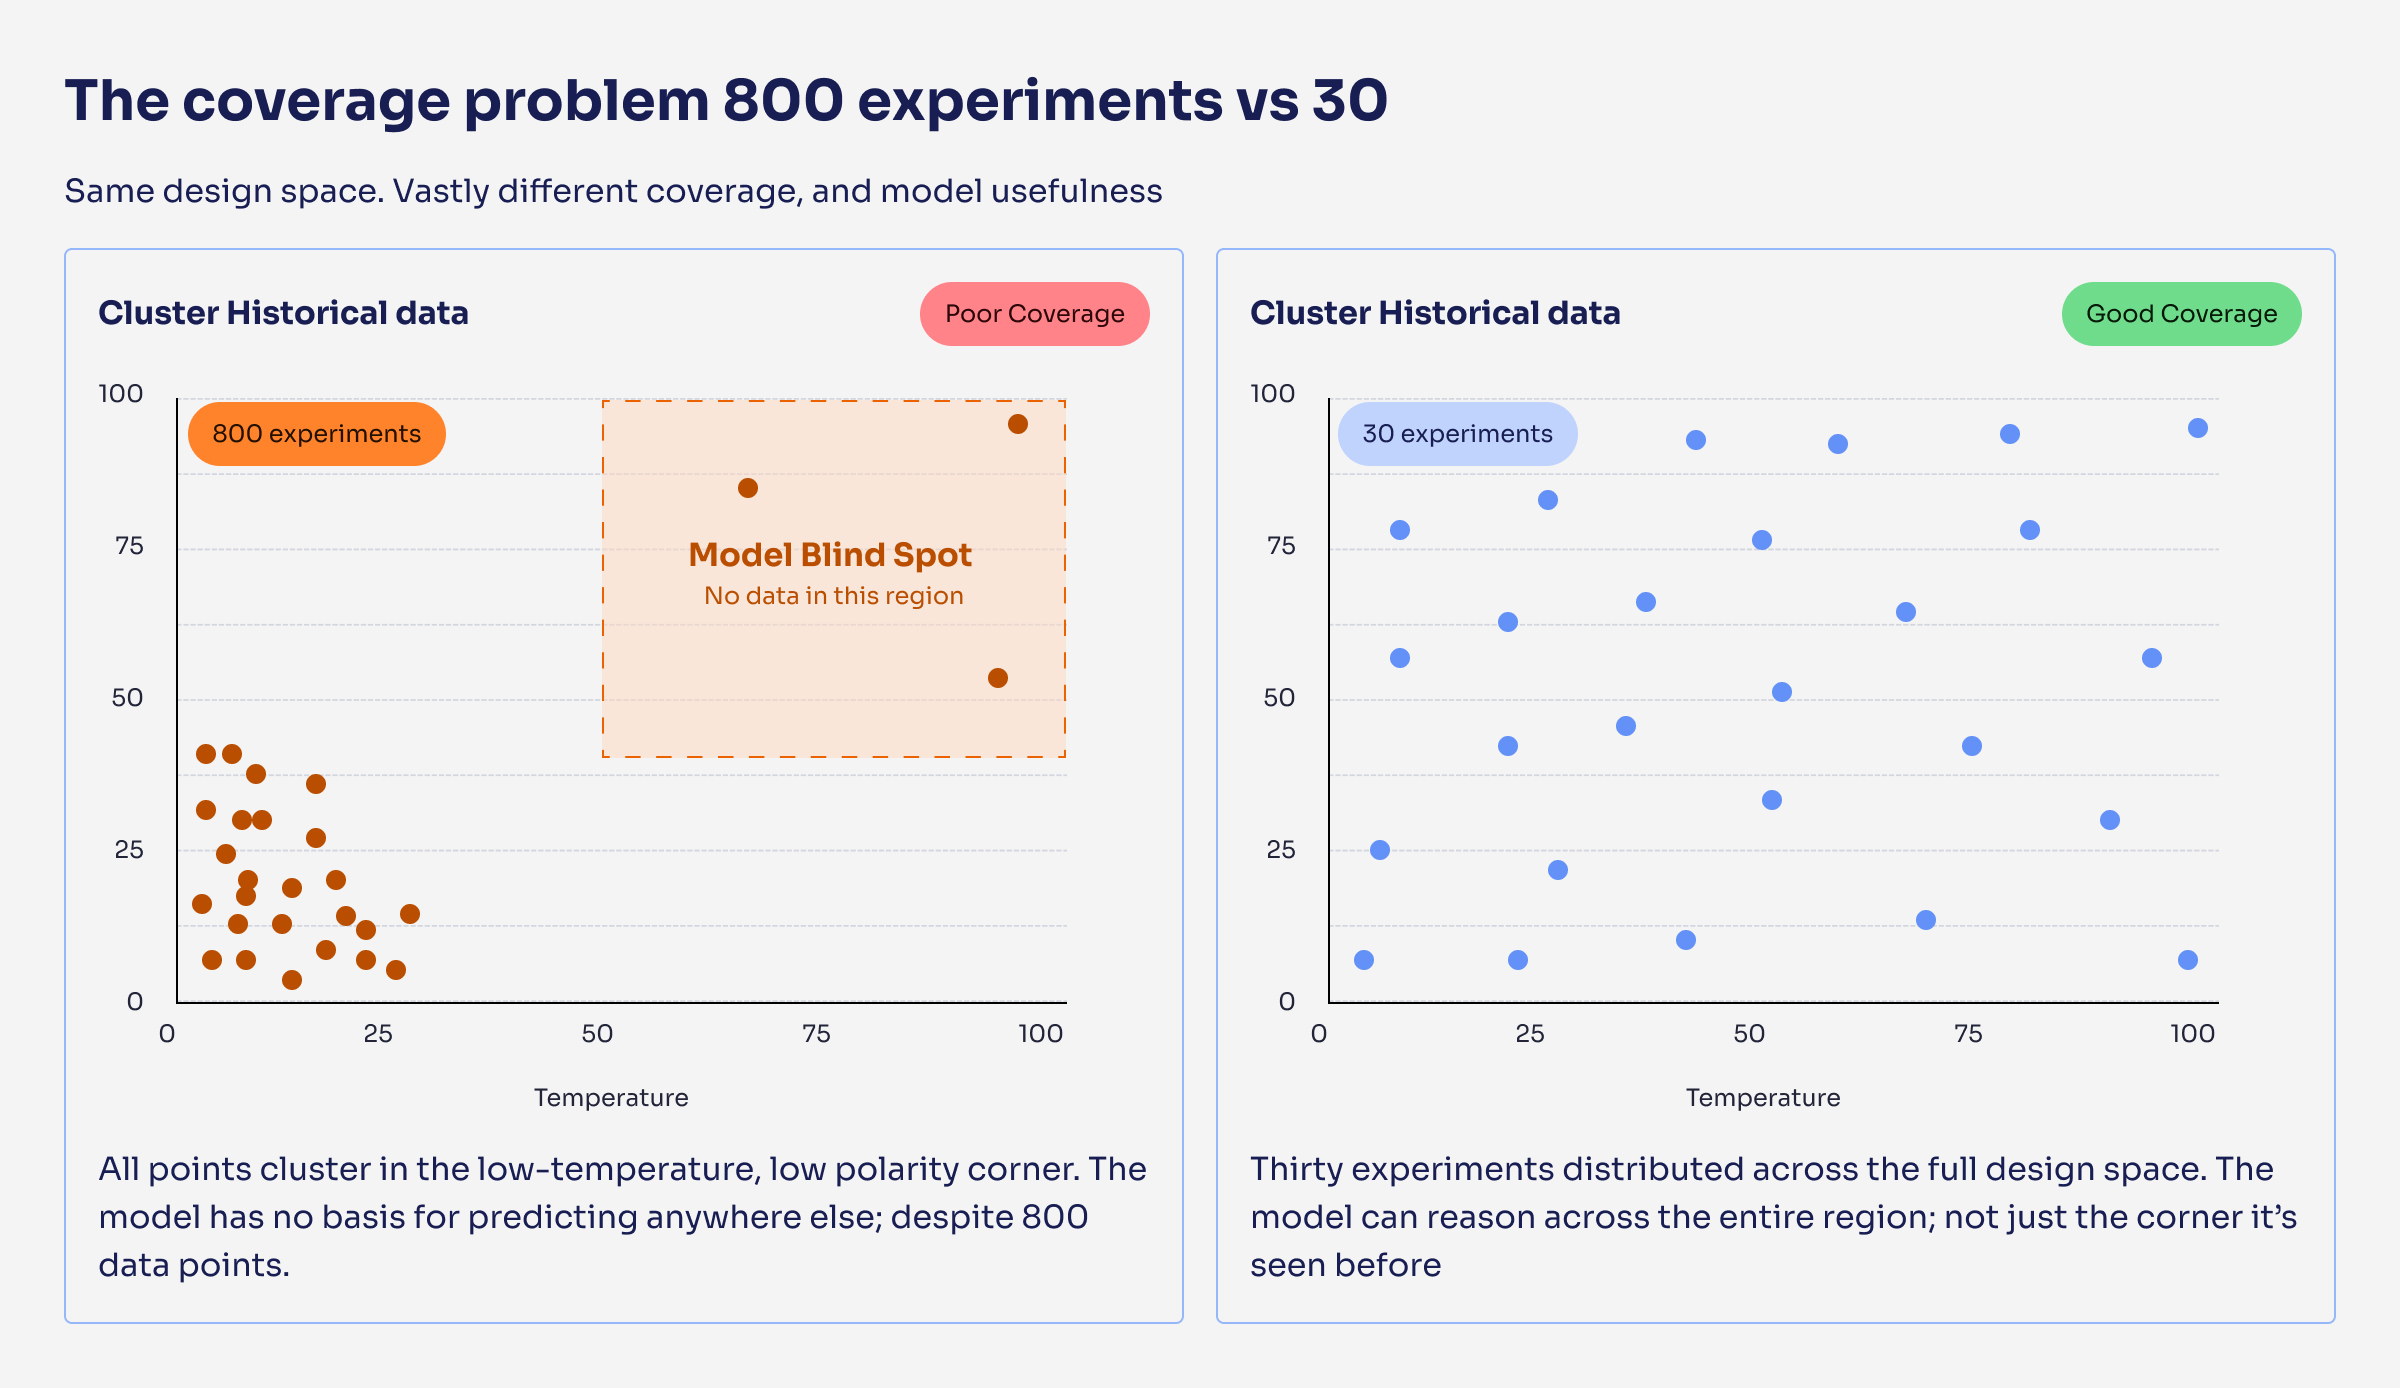
The reason the 800-row dataset was useless wasn't sample size. It was that 60% of the rows used a single solvent, the temperature column had three values across all 800 entries, and the catalyst was recorded only as labels — no descriptors, no link to chemistry.
The data was abundant and inert. A campaign run on 30 well-designed experiments would have outperformed a model trained on those 800 every time. This is the gap most R&D teams don't see until they hit it: the value of data for machine learning is not what's in the row count. It's what the data lets a model learn.
In small-data optimization — Bayesian optimization, surrogate modeling, active learning — that distinction is the difference between a campaign that converges in twenty experiments and one that never converges at all.
The dominant assumption in popular ML discourse is that data volume drives performance. For deep learning on images and text, that assumption holds. For R&D — where each experiment costs hundreds to thousands of dollars — it does not. The question for R&D teams is not "do we have enough data?" but "is the data we have informative enough to be worth modeling?"
The relevant axis is information per experiment. A 30-point dataset that systematically explores the design space will outperform a 1,000-point dataset living in one corner of that space
The Five Characteristics That Define Good Experimental Data for Machine Learning
These five attributes define whether a dataset can support a productive optimization campaign. Datasets that get all five right can drive convergence in a fraction of the experiments most teams expect. Datasets that miss two or three quietly waste years of effort.
1. Coverage
Good data spans the design space. A model can interpolate within the region it has seen; it cannot extrapolate reliably outside it. If 90% of historical experiments cluster in one corner, the model is a local model regardless of row count. The practical test: plot the data along each input dimension. Empty regions are blind spots the model will not see.
✓ All input dimensions varied systematically. No empty corners.
✗ 90% of experiments in one solvent at three temperatures.
2. Resolution
Good data has effect sizes large relative to measurement noise. If noise exceeds signal, no model recovers what is not there. This is an assay problem, not a modeling problem, and it cannot be fixed downstream.
✓ Assay standard deviation of 2%. Effects of interest are 10–20%.
✗ Yield assay standard deviation of 8%. Target effects of 3%.
3. Provenance
Good data carries its history: who ran it, on what equipment, and when. Without it, you train on noise that looks like signal. The one-chemist, one-notebook problem is a silent killer. All data generated by one person, on one piece of equipment, in one time window means whatever idiosyncrasies they introduced are now permanent features of the dataset. The model learns the chemist, not the chemistry.
✓ Every row has technician ID, equipment ID, date, and reagent batch.
✗ Three technicians and two reagent batches collapsed into one CSV.
4. Consistency
Good data follows a stable protocol. A mid-campaign protocol change creates two datasets. Combining them introduces a confound the model cannot resolve.
✓ Same workup, same instrument calibration, same objective definition throughout.
✗ Workup changed at experiment 200, not flagged. Yield definition changed from HPLC to isolated mass.
5. Structure
Good data is encoded as descriptors a model can generalize from. Labels let a model memorize. Descriptors let a model reason. Categorical-only parameterization is the most common data quality failure in R&D ML. Without parameterization, you cannot predict performance for any input the model has not already seen.
✓ Solvent: polarity, donor number, viscosity. Catalyst: steric + electronic features.
✗ Solvent: "DMSO". Catalyst: "Cat-A through Cat-E". Substrate: "SM-001 through SM-040".
Chemistry-aware parameterization — including Hansen parameters, Kamlet-Taft scales, molecular fingerprints, and computed steric and electronic features — converts labels into features a surrogate model can reason about.
Six Bad Data Patterns That Kill R&D Machine Learning Campaigns
Most teams have at least one of these. The most dangerous are the ones that do not fail loudly — they produce a model that appears to work, then performs poorly on anything new.
- The categorical-only dataset. Every input is a label: solvent A through G, catalyst 1 through 12. No descriptors, no link to chemistry. The model cannot generalize to any new input — it memorizes rather than learns. This is the most common failure pattern.
- The one-chemist, one-notebook problem. All data generated by one person, one piece of equipment, in one time window. The model learns the chemist, not the chemistry, and fails completely with new personnel. A silent killer because it does not fail during validation.
- The unmeasured confound. Yield correlates with reaction time, but reaction time also correlates with which technician ran the campaign, and the two technicians used different concentrations. The model learns a spurious correlation. Extrapolations are systematically wrong.
- The historical data graveyard. Legacy spreadsheets spanning years, multiple protocols, multiple instruments, with columns missing for half the rows. Looks like free data. The cleaning cost typically exceeds the cost of running 20–30 well-designed new experiments.
- Over-replicated, under-explored. Twenty replicates of one condition, four of another, one shot at everything else. Optimized for assay validation rather than design space exploration. Low-coverage model despite a high row count.
- The leaked-objective problem. The objective is downstream-derived from a calculation that uses input variables. The model predicts with suspicious accuracy because it's reconstructing a formula. Appears to work perfectly invalidation, fails completely on real campaigns. Hardest pattern to catch.
How Much Data You Need to Start a Bayesian Optimization Campaign?
R&D leaders ask the same question: how much data do we need to start? The honest answer for most Bayesian optimization campaigns is far smaller than teams expect coming from a deep-learning frame.
- To begin: 5–15 well-chosen seed experiments with chemistry-aware parameterization.
- To converge: 20–50 total experiments for moderate dimensionality (3–8 factors).
- Diminishing returns: 100+ experiments, where marginal value depends on whether new data explores new regions or replicates known ones
Higher dimensionality, noisier objectives, and hard constraints increase the data requirement, but the rough scale holds for most typical R&D problems.
When to Fix Bad R&D Data and When to Start Over
Fix and use: Data has good coverage and a consistent protocol, even if it lacks parameterization. Parameterization can be added retroactively from chemical databases.
Use as a prior: Data is moderately reliable but provenance is uncertain. Treat it as a region-of-interest hint rather than a primary model basis.
Start over: One-chemist-one-notebook, categorical-only inputs, multiple protocol changes, and missing covariates. Cleaning will exceed the cost of 20–30 well-designed new experiments.
The start-over option is more common than teams want to admit. Sunk-cost bias keeps bad data alive in modeling pipelines for years.
The R&D Data Quality Audit: A 10-Point Checklist
Before committing data to a machine learning campaign, run this checklist. A team that can answer all ten cleanly has a dataset worth modeling. A team that cannot has a dataset worth fixing — or worth replacing with a small, well-designed campaign.
- Coverage: Have all input dimensions been varied? Plot it.
- Signal-to-noise: What is the assay's standard deviation? Is it small relative to the effects you care about?
- Provenance: Can you identify who, when, and on what equipment for every row?
- Consistency: Has the protocol been stable? Document any breaks.
- Parameterization: Are inputs encoded as descriptors a model can generalize from?
- Confounds: Are there variables that correlate with both inputs and outputs that are not recorded?
- Leakage: Is the objective computed from features in a way that would make modeling trivial?
- Replicate balance: Is the dataset over-weighted on replicates of a few conditions?
- Historical hygiene: If using legacy data, is each row's source traceable?
- Objective definition: Is the target metric defined consistently across all rows?
Conclusion
The most consistent reason machine learning fails in R&D is not the model. It is the data the model was given. Experimental data quality is defined by five things: coverage, resolution, provenance, consistency, and structure.
The most useful exercise for any R&D team about to commit to a modeling project is the half-day data audit: run the ten-point checklist, identify what is missing, and decide whether to fix, supplement, or restart. That conversation, done early, is worth more than any model selection decision that follows.
The most consistent reason machine learning fails in R&D is not the model. It's the data the model was given.
If you want to see how chemistry-aware parameterization works on your actual data, contact us to discuss your campaign and timeline.
Frequently Asked Questions
How much data do you need for Bayesian optimization?
For a small-to-moderate dimensional problem (3–8 factors), 5–15 well-chosen seed experiments is enough to start, and 20–50 is usually enough to converge. Quality of parameterization matters more than row count.
Is more data always better for R&D machine learning?
No. More data with the same blind spots, the same protocol issues, and the same poor parameterization produces the same problem at higher cost. More data only helps if it fills gaps the existing data does not cover.
What is the single biggest data quality mistake in R&D ML?
Categorical-only parameterization. Encoding chemicals as labels rather than descriptors prevents the model from generalizingto anything new.
Can you use legacy historical data for a Bayesian optimization campaign?
Sometimes. Use legacy data to inform priors and identify regions of interest, but be cautious about training models on itdirectly. Protocol drift, missing covariates, and untracked confounds make legacy data unreliable as a primary modelingsource.
How do you know if your assay is good enough for ML?
Run replicates of a representative condition and compute the standard deviation. Compare it to the effect sizes you care about.If the noise is comparable to the signal, the assay is the bottleneck, not the model.
Is high-throughput experimentation data automatically good data for ML?
Not automatically. HTE produces volume, but it can also amplify protocol drift, dilute provenance, and over-explore narrowregions. The same five characteristics apply — they are just easier to violate at scale.
Further Reading
- Wilkinson, M. D., et al. (2016). The FAIR Guiding Principles for scientific data management and stewardship. Scientific Data, 3,160018.
- Kapoor, S., & Narayanan, A. (2023). Leakage and the reproducibility crisis in machine-learning-based science. Patterns, 4(9),100804.
- Sculley, D., et al. (2015). Hidden Technical Debt in Machine Learning Systems. NeurIPS.
- Shields, B. J., et al. (2021). Bayesian reaction optimization as a tool for chemical synthesis. Nature, 590, 89–96.5. Hansen, C. M. (2007). Hansen Solubility Parameters: A User's Handbook. CRC Press.